
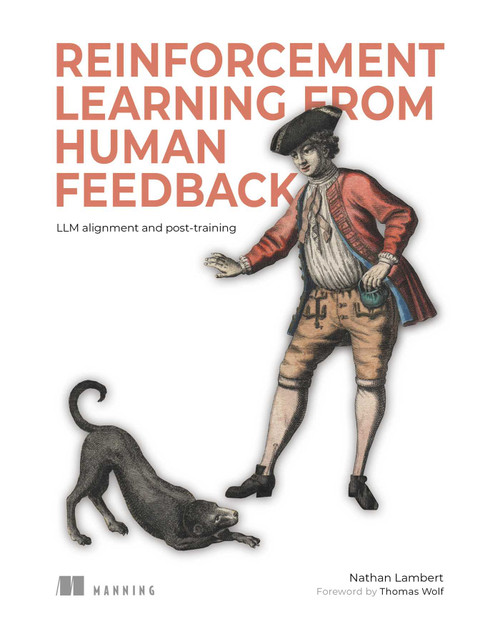
Reinforcement Learning from Human Feedback: LLM alignment and post-training
$50.99 / copy at 25+ copies As low as $47.99 at 1,000+Your best volume price
Total $1,274.75
Format
The more copies, the less each one costs
Applied automatically in your cart. No code needed.
Turn this order into a program
Groups that order together often pair the copies with something more. We handle the extras so you don't have to.
Branded cover stickers on paperbacks from 100 copies, plus bookplates, inserts and belly bands. Your specialist confirms what fits your title.
Customization options Ship to every readerOne address, many sites or individual recipients' homes, in the US and abroad.
Fulfillment options Pair it with a branded journalJournals with your logo or each reader's name, for the same group.
Branded journals Bring in a speaker
BookPal is partnering with Talezo to help you find and book authors, speakers and performers for your event.
BookPal × TalezoReinforcement Learning from Human Feedback
"A masterful synthesis of the field’s intellectual roots and its practical tools.”
—Saurabh Sawant, Microsoft
Reinforcement Learning from Human Feedback: LLM alignment and post-training helps you understand how modern AI models can be adapted to better match the needs and expectations of their users. Rather than surveying the vast field of reinforcement learning, elite AI researcher Nathan Lambert concentrates exclusively on RLHF and its immediate importance to post-training generative AI models.
This compact book gets right to the point. Early chapters establish the training overview, explain instruction fine-tuning, and build reliable reward models. The middle chapters transition into the heart of alignment, exploring core policy gradient algorithms, Direct Preference Optimization (DPO), and inference-time scaling. Later chapters tackle the messy reality of data, guiding you through preference data collection, synthetic data generation, and the nuances of function calling.
As you go, you will see how these post-training methods actually work, including their unique compute costs and latency trade-offs. You will explore common failure modes, such as qualitative over-optimization, reward hacking, and the unreliability of external evaluation comparisons. Difficult concepts like KL regularization, proximal policy optimization, and generative reward modeling are clarified with hands-on experiments.
Reinforcement Learning from Human Feedback avoids irrelevant academic details in favor of immediate, practical value. Everything author Nathan Lambert includes appears because a modern RLHF project requires it. He skillfully explains complex post-training pipelines by making every detail concrete, connecting isolated abstractions directly to the goal of making models safer, smarter, and perfectly tuned to a desired style.
The book’s seventeen short chapters lay out the core material, while supplements like vocabulary definitions, compute cost management, evaluation variance, and training performance tracking appear in handy appendixes. The result is a logically flowing book that remains highly navigable and technically deep without getting bogged down in unnecessary theory.
The book covers
• Core RLHF implementations and Direct Alignment Algorithms
• Building robust preference and synthetic data pipelines
• Evaluating models and crafting specific AI personas
About the reader
For established engineers, AI scientists, and students trying to get a practical foothold in AI model alignment.
About the author
Dr. Nathan Lambert is a leading AI researcher known for leading post-training at the Allen Institute for AI. With previous experience at HuggingFace, DeepMind, and Meta, he is a passionate advocate for open models. His work focuses on increasing access to, and the understanding of, AI technology—empowering readers to contribute to the advancement of AI outside closed corporate labs.
Table of Contents
Part 1
1 Introduction
2 A tiny history of RLHF
3 Training overview
Part 2
4 Instruction fine-tuning
5 Reward modeling
6 Reinforcement learning
7 Reasoning and inference-time scaling
8 Direct-alignment algorithms
9 Rejection sampling
Part 3
10 The nature of preferences
11 Preference data
12 Synthetic data
Part 4
13 Tool use and function calling
14 Over-optimization
15 Regularization
16 Evaluation
17 Crafting model character and products
A Definitions
B Beyond “just style”
C Practical Issues
The book, Reinforcement Learning from Human Feedback: LLM alignment and post-training [Bulk, Wholesale, Quantity] ISBN#9781633434301 in Paperback by Nathan Lambert may be ordered in bulk quantities. Minimum starts at 25 copies. Availability based on publisher status and quantity being ordered.
Details
- Publisher
- Manning
- Author
- Nathan Lambert
- Format
- Paperback
- Published
- Aug 4, 2026
- ISBN-13
- 9781633434301
- ISBN-10
- 1633434303
- Pages
- 312
Reinforcement Learning from Human Feedback for groups: pricing
Volume pricing applies automatically in your cart. No codes, no account needed.
| Copies | Price per copy | You save |
|---|---|---|
| 25 – 99 | $50.99 | 15% off list |
| 100 – 249 | $50.39 | 16% off list |
| 250 – 499 | $49.79 | 17% off list |
| 500 – 999 | $49.19 | 18% off list |
| 1,000+ | $47.99 | 20% off list |
Popular for
A copy for every member, on one order.
A book for every attendee, delivered to your venue.
For clients, staff, members or volunteers.
What does Reinforcement Learning from Human Feedback cost when I buy for a group?
Volume pricing applies automatically in your cart, with no code needed. Price per copy: 25 to 99 copies, $50.99 (15% off list); 100 to 249 copies, $50.39 (16% off list); 250 to 499 copies, $49.79 (17% off list); 500 to 999 copies, $49.19 (18% off list); 1,000+ copies, $47.99 (20% off list). Need a different quantity, or a quote to forward for approval? Ask a specialist and we will confirm pricing before you pay.
How fast can I get copies of Reinforcement Learning from Human Feedback?
Need them by a specific date? Request a quote and we'll confirm timing before you pay.
Can you ship to several locations or people's homes?
Yes. We ship group orders to one address, to multiple sites, or to individual recipients, in the US and internationally. See fulfillment options.
Can I get a formal quote for approval before ordering?
Yes. Request a quote and we'll send a PDF you can forward for approval.
Do you accept purchase orders and tax-exempt orders?
Yes. We accept purchase orders upon approval, as well as cards, PayPal, ACH, wire transfers and checks. BookPal is a tax-exempt supplier in all 50 states. See purchase orders and sales tax exemption.
What if I find a lower price?
Send us the link. We match prices from other booksellers and distributors on a new copy in the same edition, available to ship in the quantity you need. Clearance sales and pricing errors are the exception, and we'll tell you quickly if that's the case. Start a price match.
Write a Review
Reinforcement Learning from Human Feedback: LLM alignment and post-training
Groups also order

A colleague asked you to approve this order
Your quote list
Add books as you browse, then request one quote for all of them.